Future of List Crawler: Industry Insights
What Industry Leaders Are Saying About the Future of List Crawler Technology

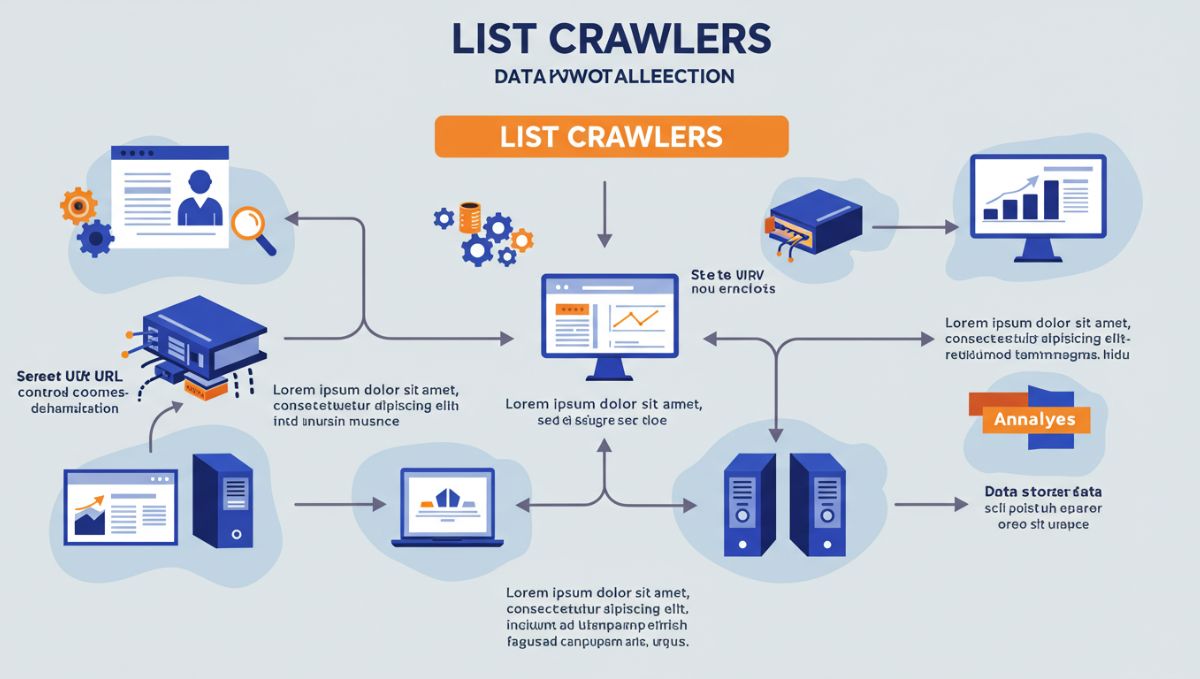
Data is the lifeblood of modern digital strategy. Whether you are fueling machine learning models, conducting market research, or tracking competitor pricing, automated data collection tools are essential. Among these, the list crawler remains a foundational asset for gathering structured information at scale. However, as web architectures grow more complex and anti-scraping measures advance, the traditional approach to crawling is undergoing a massive transformation.
To understand where this technology is heading, we spoke with CTOs, data engineers, and scraping infrastructure architects. Their insights reveal a landscape shifting away from brittle, rule-based scripts toward intelligent, adaptive systems powered by artificial intelligence.
The Shift Toward AI-Driven Extraction
For over a decade, list crawlers relied heavily on rigid HTML selectors, XPath expressions, and regular expressions. If a target website updated its layout, the crawler would break, requiring manual intervention from a developer. Industry leaders agree that this era of maintenance-heavy scraping is coming to an end.
Self-Healing Parsers and Dynamic Adaptation
Leading data engineers point to machine learning models as the primary driver of change. Modern list crawlers increasingly utilize computer vision and Large Language Models (LLMs) to understand page content the way a human does.
Instead of looking for a specific `
Intent-Based Crawling
Rather than blindly downloading entire sites or long pagination sequences, next-generation crawlers are becoming more selective. CTOs emphasize the rise of intent-based architectures, where the crawler determines the most efficient path to retrieve target datasets based on user queries, saving both bandwidth and computational power.
Navigating Anti-Bot Measures and Compliance
As list crawlers become more sophisticated, so do the defensive mechanisms deployed by website owners. Web Application Firewalls (WAFs), CAPTCHAs, and behavioral analysis tools are standard across most high-value platforms. Industry experts emphasize that the future belongs to those who balance technical capability with ethical practices.
- Ethical Scraping and Rate Limiting: Leaders stress the importance of respecting `robots.txt` files and implementing intelligent rate limiting to avoid disrupting target servers.
- Advanced Proxy Management: Residential and mobile proxy networks are no longer optional for large-scale operations; they are standard requirements for avoiding IP bans.
- Headless Browser Fingerprinting: Modern crawlers must manage browser fingerprints (TLS, canvas, and WebGL parameters) to mimic genuine user sessions seamlessly.
At the same time, legal frameworks like GDPR and CCPA continue to evolve. Experts note that future list crawler tools must incorporate automated data anonymization and strict compliance filters to ensure that personally identifiable information (PII) is filtered out at the point of collection.
Integration with Real-Time Data Pipelines
In the past, list crawlers operated as batch processors—running overnight dumps that were then loaded into data warehouses the following morning. Today, business intelligence moves faster.
Enterprise data architects highlight a growing demand for real-time streaming data integration. Modern crawlers are increasingly built to feed directly into streaming platforms like Apache Kafka or AWS Kinesis. This allows organizations to trigger automated workflows the moment a new item appears on a target list, whether it's a newly listed real estate property, a stock price fluctuation, or a fresh job posting.
The Democratization of Data Extraction
Another major theme among industry veterans is the democratization of web data. Historically, deploying and maintaining a robust list crawler required specialized software engineers. Today, low-code and no-code platforms are putting these capabilities into the hands of non-technical professionals.
Product managers, marketers, and financial analysts can now configure complex data collection workflows through intuitive graphical user interfaces. Behind the scenes, cloud infrastructure handles the heavy lifting of proxy rotation, JavaScript rendering, and error handling.
Conclusion: Preparing for the Next Generation of Data Collection
The consensus among industry leaders is clear: the future of the list crawler lies at the intersection of artificial intelligence, automated resilience, and real-time data streaming. While technical challenges around anti-bot systems and regulatory compliance will continue to grow, the tools available to data professionals are becoming exponentially smarter and more adaptable.
Organizations that embrace AI-driven extraction and maintain strict adherence to ethical crawling standards will secure a distinct competitive advantage, turning raw web data into actionable intelligence with unprecedented speed and reliability.