How to Run Trino Multi Insert Python Queries
When building modern data platforms, data engineers often need to route incoming streams or batch datasets into multiple destination tables simultaneously. Doing this efficiently prevents redundant table scans and slashes ETL runtime. If you are using a distributed SQL query engine like Trino, you can leverage SQL's multi-table insert syntax. Managing this workflow programmatically is where a trino multi insert python automation script comes into play.
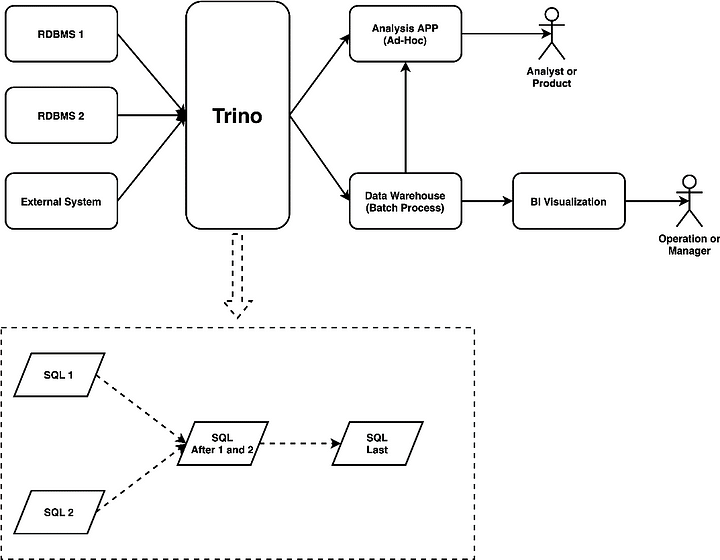
This article guides you through setting up the Trino Python client, constructing an optimal multi-insert query, and executing it reliably within your Python data pipelines.
Understanding Trino Multi-Insert Queries
A multi-insert statement allows you to evaluate a source dataset a single time and insert the resulting rows into two or more target tables based on specific conditions or matching schemas. In standard Trino SQL, this syntax looks like:
FROM source_table
EXCEPTIONS / WHERE conditions...
INSERT INTO target_table_a (col1, col2) SELECT col1, col2 WHERE category = 'A'
INSERT INTO target_table_b (col1, col2) SELECT col1, col2 WHERE category = 'B';
By using this approach instead of running separate INSERT INTO statements, Trino reads the source table only once. This significantly reduces I/O overhead, which is critical when working with massive data lakes stored in formats like Iceberg, Delta Lake, or Hive.
Prerequisites and Environment Setup
Before writing Python code to interact with your cluster, ensure you have the necessary libraries installed. The official client for connecting Python applications to Trino is the trino-python-client.
Run the following command in your terminal to install it via pip:
pip install trinoYou will also need:
- A running Trino coordinator and worker cluster.
- Appropriate catalog, schema, and table write permissions.
- Network access to your Trino coordinator's port (typically 8080).
Implementing Trino Multi Insert Python Scripts
Video: building trino data pipelines with sql or python

To execute a multi-insert query from Python, you establish a connection using the trino.dbapi module, create a cursor, and pass your multi-statement SQL string to the execute() method.
Basic Connection and Execution Example
Here is a complete, production-ready script demonstrating how to run a multi-insert operation:
import trino

# Establish connection to the Trino coordinator
conn = trino.dbapi.connect(
    host='your-trino-coordinator.company.com',
    port=8080,
    user='data_engineer',
    catalog='hive',
    schema='gold_layer',
)

cursor = conn.cursor()

# Define the multi-insert SQL statement
multi_insert_query = """
    FROM silver_layer.web_events
    INSERT INTO gold_layer.events_mobile
        SELECT event_id, user_id, timestamp, page
        WHERE device_type = 'mobile'
    INSERT INTO gold_layer.events_desktop
        SELECT event_id, user_id, timestamp, page
        WHERE device_type = 'desktop'
"""

try:
    print("Executing multi-insert query...")
    cursor.execute(multi_insert_query)

    # Fetch results if any (usually empty for insert statements, but good practice to consume)
    rows = cursor.fetchall()
    print("Multi-insert completed successfully.")

except Exception as e:
    print(f"An error occurred during execution: {e}")

finally:
    cursor.close()
    conn.close()
Handling Parameters and Dynamic Queries
Hardcoding table names or filter parameters inside strings can make your scripts rigid. Often, you will want to generate these queries dynamically based on configuration files, dates, or workflow parameters from orchestrators like Apache Airflow.
When injecting dynamic values into your SQL string, always sanitize inputs or use safe formatting to prevent SQL injection vulnerabilities. Here is how you can parameterize a date range for a multi-insert workflow:
import trino

def run_partitioned_multi_insert(target_date: str):
    conn = trino.dbapi.connect(
        host='localhost',
        port=8080,
        user='etl_bot',
        catalog='iceberg',
        schema='analytics'
    )

    cursor = conn.cursor()

    # Safely formatting dynamic partition values into the query
    query = f"""
        FROM raw_events
        WHERE dt = '{target_date}'
        INSERT INTO region_americas
            SELECT event_id, user_id, payload
            WHERE region = 'AMER'
        INSERT INTO region_EMEA
            SELECT event_id, user_id, payload
            WHERE region = 'EMEA'
    """

    cursor.execute(query)
    cursor.close()
    conn.close()

# Run for yesterday's partition
run_partitioned_multi_insert('2023-10-25')
Best Practices and Performance Tuning
When running complex multi-table inserts across distributed storage, keeping a few best practices in mind will ensure your queries finish quickly and don't overwhelm your cluster resources.
- Minimize Output Files: Distributed engines can create many small files when writing data concurrently. Ensure your target tables use file compaction or optimized storage formats like Apache Iceberg.
- Monitor Memory Usage: Multi-insert queries hold intermediate results in memory longer as they evaluate multiple branches. Keep an eye on your Trino coordinator and worker memory metrics via the Web UI.
- Use Appropriate Partitioning: Ensure that your source table is partitioned efficiently (e.g., by date) so that Trino can apply partition pruning before executing the insert logic.
- Error Handling: Wrap your database operations in robust
try-exceptblocks to catch network drops, timeout issues, or syntax errors returned by the Trino API.
Conclusion
Integrating a trino multi insert python workflow into your data architecture allows you to streamline ETL pipelines, reduce cluster load, and maintain clean separation of data downstream. By combining the Trino Python client with optimized multi-table SQL statements, you can build fast, scalable, and maintainable data ingestion pipelines.