List Crawlers DC for Complete Success
In the heart of the nation's capital, organizations thrive on accurate, real-time data. Whether you are tracking federal policy changes, conducting market research, or gathering competitive intelligence, manual data collection simply cannot keep pace. That is why professionals across industries rely on specialized tools to List Crawlers DC for Complete Success.

Web scraping and crawling technologies allow businesses and researchers to automate the extraction of vast amounts of information from websites. However, deploying a crawler effectively requires a strategic approach. This guide explores how to identify, configure, and utilize web crawlers in the Washington, D.C. market to achieve your operational goals.
Understanding the Role of Crawlers in Data Strategy
Before launching any data collection initiative, it is vital to understand what web crawlers do and how they fit into your broader data architecture. A crawler (often called a spider or bot) systematically browses the World Wide Web, typically for the purpose of web indexing or data harvesting.
In a fast-paced environment like Washington, D.C., having access to up-to-date data provides a distinct competitive edge. From tracking legislative updates on government portals to monitoring local business directory listings, automated crawlers save hundreds of manual work hours while reducing human error.
How to List Crawlers DC for Complete Success
Building a successful web scraping pipeline is not just about writing code; it involves careful planning, tool selection, and adherence to legal and ethical standards. Here is a step-by-step roadmap to organizing and deploying your crawling strategy in the D.C. area.
1. Define Your Data Objectives
Every successful crawling project starts with a clear question. What specific data points do you need? Are you looking for contact information for local government contractors, real estate listings, or public procurement notices?
- Identify target websites and domains.
- Determine the exact frequency of data updates required (real-time, daily, weekly).
- Outline how the data will be stored, cleaned, and analyzed.
2. Choose the Right Crawling Tools
Selecting the right software framework or cloud-based scraper depends on your technical expertise and project scale. D.C. enterprises often choose between custom-built scripts and enterprise-grade crawling platforms.
- Python Libraries (BeautifulSoup, Scrapy): Ideal for developers who need maximum customization and control over complex DOM structures.
- No-Code Scrapers (Octoparse, ParseHub): Perfect for analysts who want to extract data quickly without writing code.
- Enterprise APIs (Apify, Crawlbase): Best for large-scale operations requiring proxy rotation and anti-bot bypass capabilities.
3. Implement Robust Proxy and IP Management
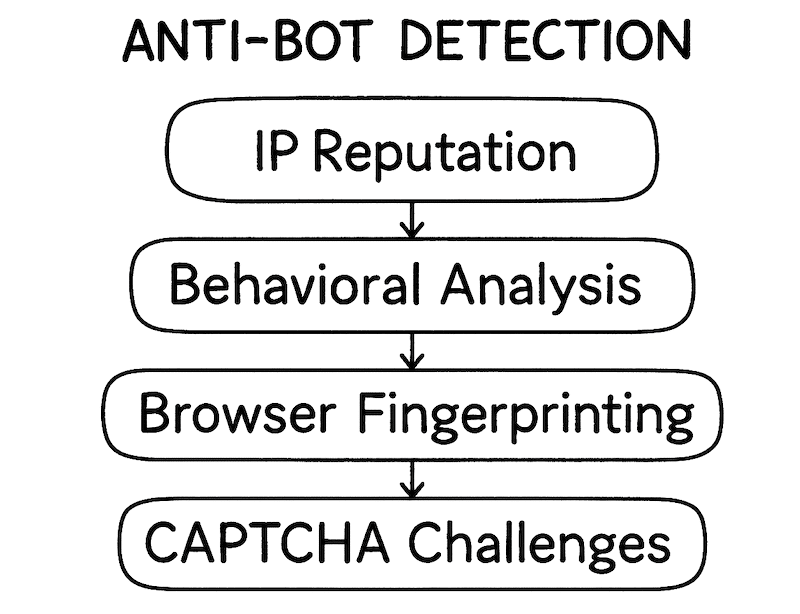
Websites frequently block suspicious traffic or automated bots. If your crawler gets blocked, your data pipeline halts. To ensure uninterrupted collection, you must manage your IP addresses carefully.
Utilize rotating residential proxies located within the United States—or specifically targeted regions—to mimic authentic human browsing behavior. This prevents rate-limiting and ensures your crawler can access geo-restricted or security-heavy public portals.
4. Respect Robots.txt and Legal Guidelines
Data collection must be conducted responsibly. In the United States, public web scraping is generally legal, but courts have placed caveats on how data is harvested and used.
- Always check a website’s
robots.txtfile to see which paths the site owner prefers crawlers to avoid. - Avoid scraping private data, copyrighted content, or personally identifiable information (PII) without explicit consent.
- Do not overload target servers with aggressive request rates that could mimic a Denial of Service (DoS) attack.
Cleaning and Processing Your Extracted Data
Raw data collected by crawlers is rarely ready for immediate analysis. It usually contains duplicates, formatting inconsistencies, and irrelevant HTML tags. Integrating a data cleaning step into your workflow is crucial for success.
Use data manipulation libraries like Pandas in Python or SQL queries to normalize dates, remove duplicate records, and structure the output into clean CSV, JSON, or database formats. High-quality data ensures that your downstream business intelligence tools generate reliable insights.
Scaling Your Crawling Operations
As your organization grows, your data requirements will expand. Scaling a crawling operation involves moving from local machines to cloud-based infrastructure (such as AWS, Google Cloud, or Azure). Cloud environments allow you to run multiple crawler instances in parallel, drastically reducing the time required to harvest large datasets across thousands of web pages.
Conclusion
Mastering web data extraction requires a blend of the right tools, ethical practices, and technical foresight. By taking the time to carefully plan, configure, and maintain your scraping infrastructure, you can successfully List Crawlers DC for Complete Success. Embrace automated intelligence today to keep your organization ahead of the curve in Washington, D.C.'s competitive landscape.