Mastering The Macon List Crawling Esteem
In the evolving landscape of web development and search engine optimization, technical precision dictates visibility. Among the myriad strategies deployed by data analysts and developers, understanding unique concepts like The Macon List Crawling Esteem provides a distinct competitive edge. Whether you are auditing a massive enterprise website or refining a targeted web scraping script, how search engines and custom bots traverse digital directories matters profoundly.
This article explores the mechanics behind advanced web crawling methodologies, how structured lists influence bot behavior, and why maintaining high digital esteem is critical for modern web architectures.
Understanding Web Crawling Mechanics
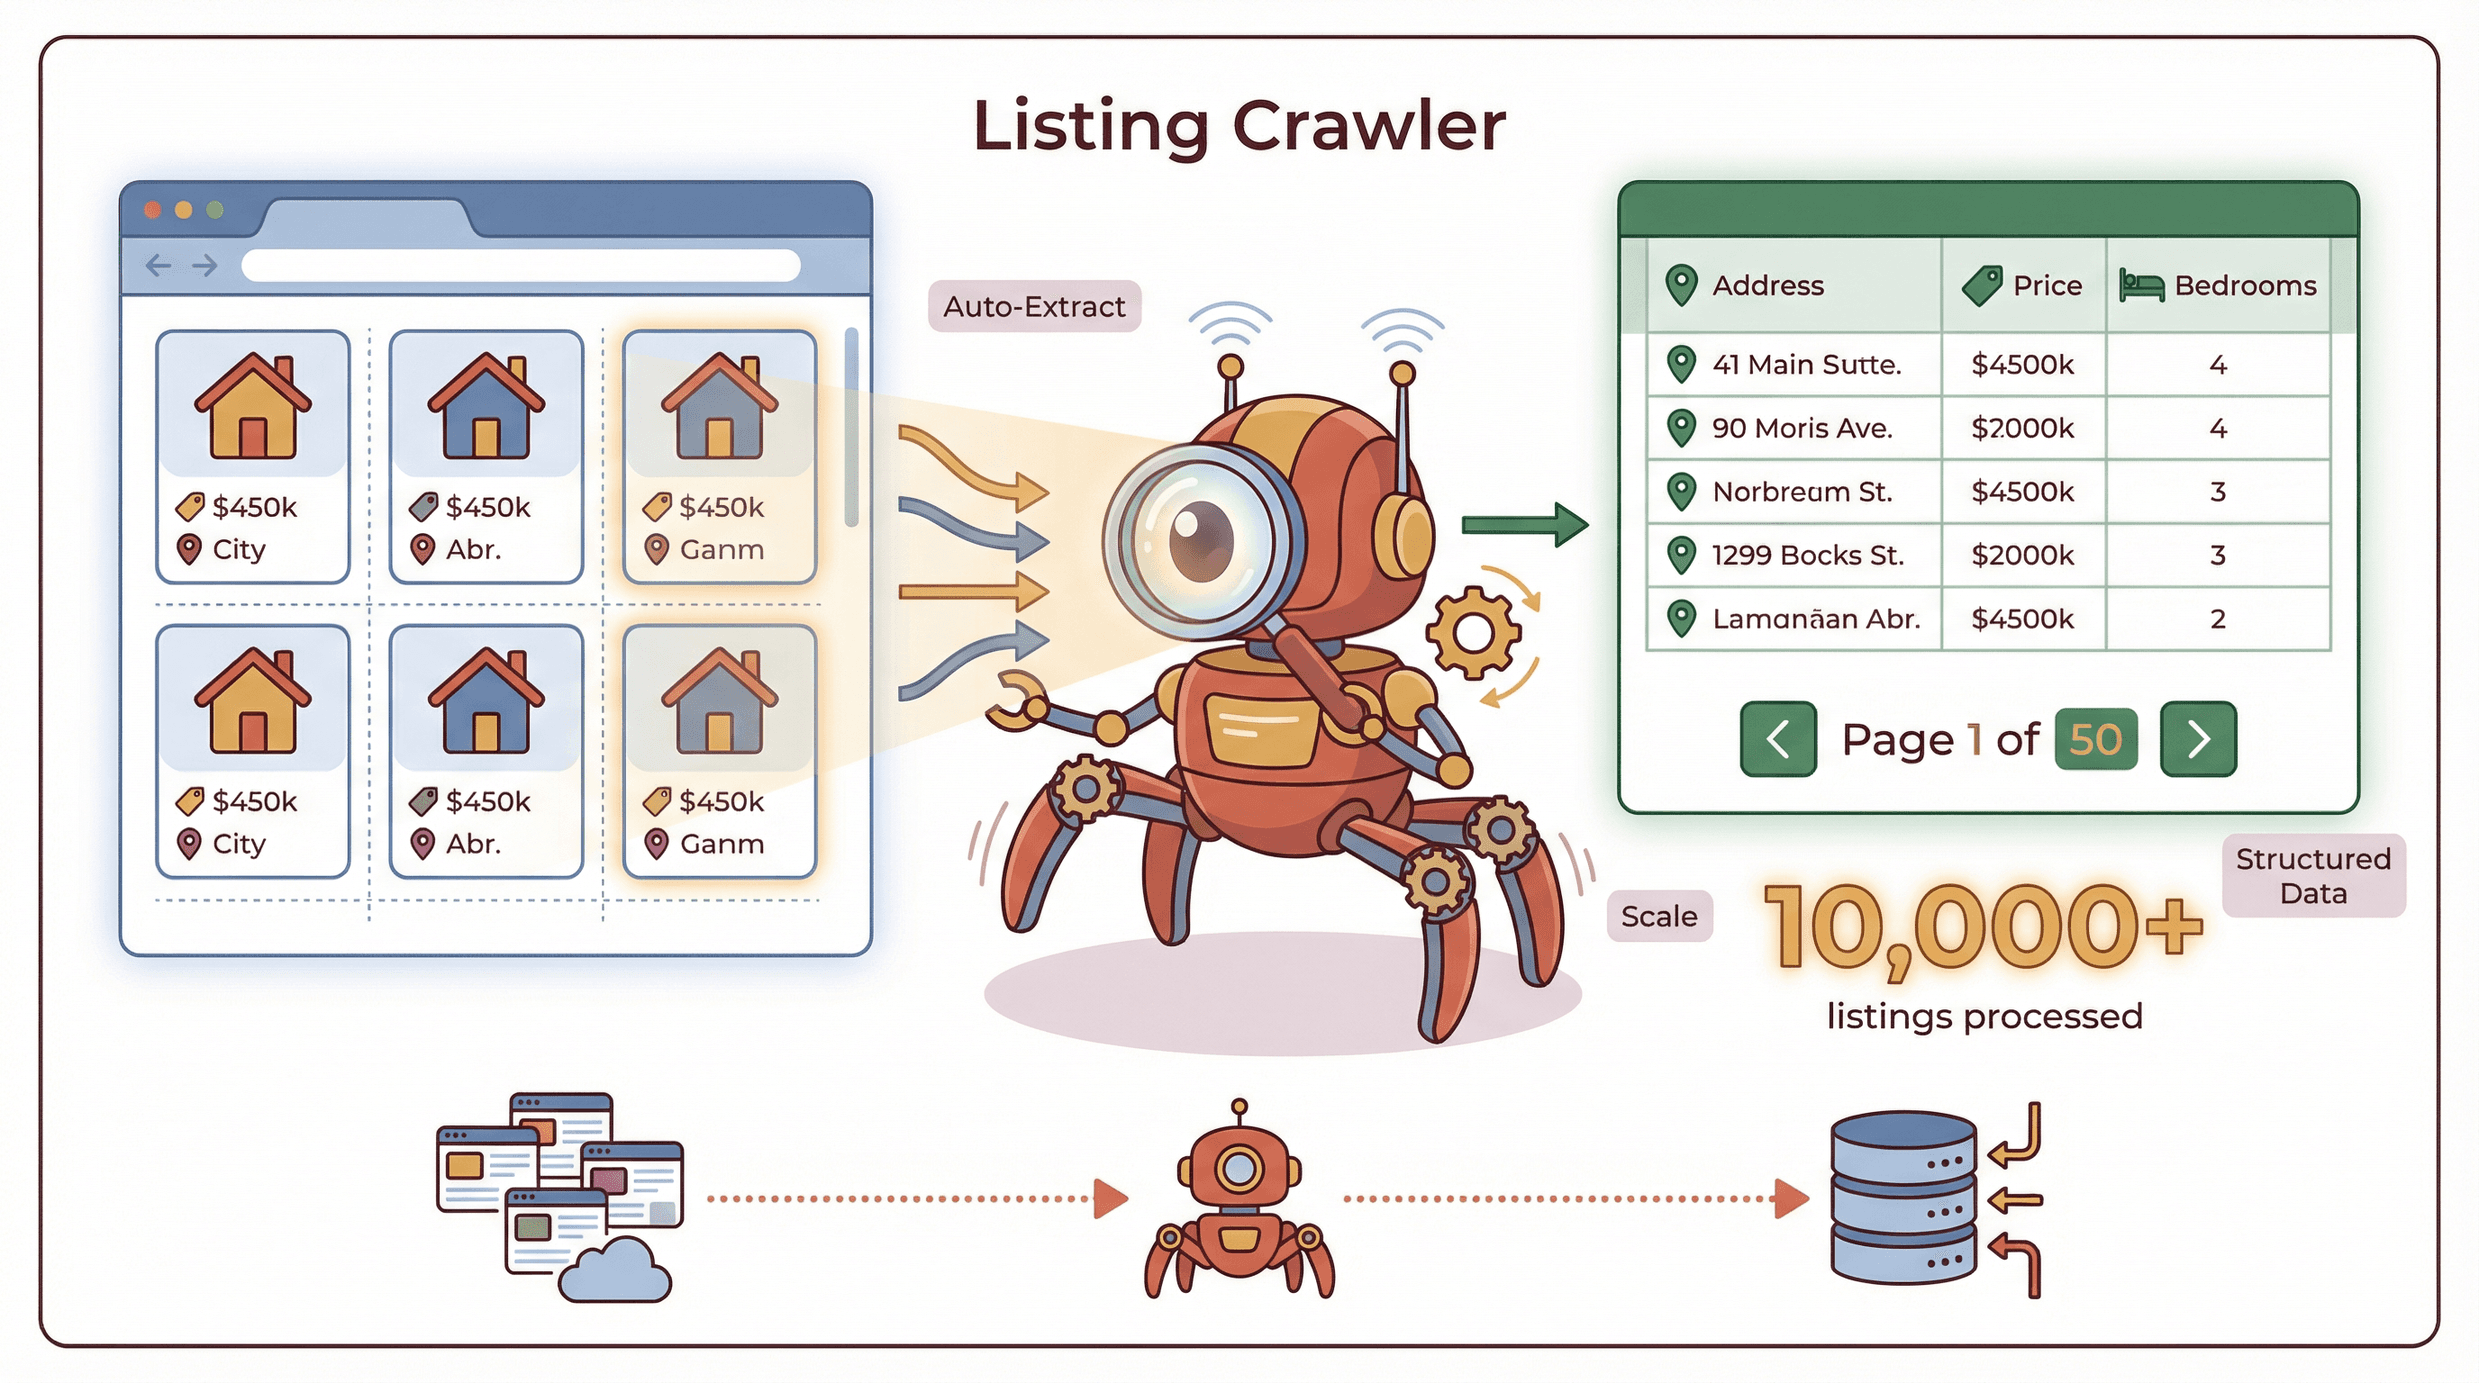
Web crawlers—often referred to as spiders or bots—are automated scripts designed to systematically browse the internet. They start with a seed list of URLs, parse the HTML content, extract hyperlinks, and follow them to discover new pages. This recursive process forms the backbone of search engine indexing and large-scale data harvesting.
However, not all crawl paths are treated equally. Search engines allocate a finite amount of resources, known as crawl budget, to individual domains. If a site features bloated directories, broken internal links, or unstructured data, bots waste valuable resources. This is where strategic curation and optimization come into play.
The Significance of The Macon List Crawling Esteem
The term The Macon List Crawling Esteem speaks to a specific philosophy in technical SEO and data management: the prioritization, validation, and authoritative weighting of curated URL lists during the extraction or indexing phase. When bots evaluate a structured list of pages, their traversal efficiency depends entirely on the structural integrity and contextual relevance of those targets.
High "crawling esteem" means that a domain or a specific directory list is trusted by automated agents to deliver low-error, high-value content consistently. When search engine bots or custom scrapers recognize that a list is well-maintained, free of duplicate traps, and logically organized, they allocate more processing power and frequency to indexing it.
Key Factors Influencing Crawl Esteem

To build and maintain high crawl esteem for your targeted directory lists, several technical pillars must be addressed:
- Server Response Times: Rapid 200 OK statuses encourage bots to go deeper into the list without timing out.
- Logical Hierarchy: Clear parent-child directory structures allow crawlers to understand context quickly.
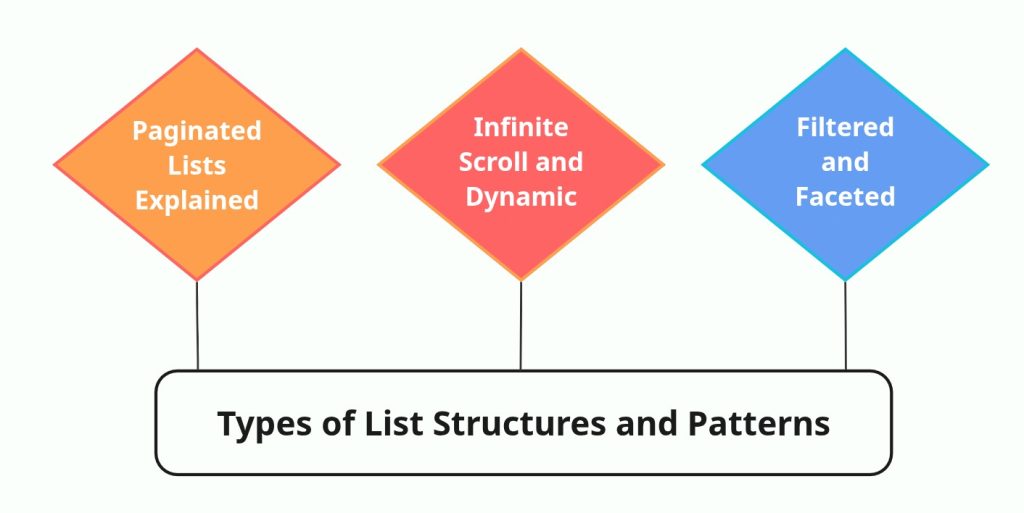
- Clean Pagination: Proper use of rel=next and rel=prev tags, or infinite scroll optimization, prevents endless loops.
- XML Sitemap Accuracy: Ensuring that listed URLs match canonical versions reduces wasted crawl cycles.
Best Practices for Optimizing Bot Traversal
Improving how automated scripts interact with your digital assets requires a proactive approach. By implementing standardized protocols, you can ensure that your priority pages receive maximum attention from both search engines and custom data pipelines.
- Audit Your Internal Linking: Eliminate orphan pages by ensuring every important URL is reachable within three clicks from the homepage.
- Leverage robots.txt Wisely: Block low-value utility pages, admin logins, and staging environments to preserve crawl budget for your core content lists.
- Monitor Log Files: Analyze server logs regularly to see how often bots visit specific URLs and where they encounter errors like 404s or 5xx server faults.
- Implement Caching Strategies: Use edge caching and content delivery networks (CDNs) to reduce server load during heavy crawling sessions.
Common Pitfalls to Avoid
Even experienced developers sometimes fall into traps that degrade their site's technical standing. Creating massive lists of low-value, thin-content pages can trigger quality filters in search engines. Similarly, deploying poorly coded JavaScript that hides important links behind complex user interactions can blind crawlers entirely.
Always ensure that critical navigation elements are rendered in server-side HTML. If a bot cannot parse a link on initial inspection, its estimated value drops dramatically, directly harming your overall visibility and data retrieval efficiency.
Conclusion
Mastering technical data navigation requires more than just basic XML sitemaps. By embracing the principles behind The Macon List Crawling Esteem, developers, SEO professionals, and data engineers can build resilient architectures that satisfy automated bots. Prioritizing server health, logical list structures, and clean internal linking ensures your web assets remain visible, accessible, and highly valued in the digital ecosystem.