The Macon List Crawling Zeal: A Complete Guide
Understanding The Macon List Crawling Zeal
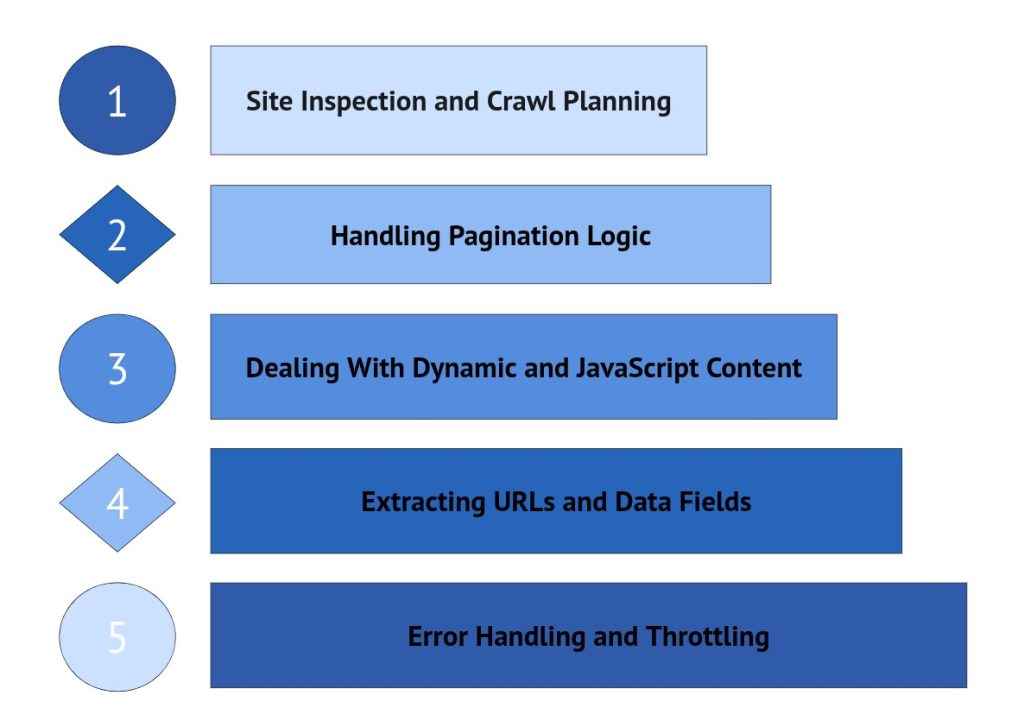
Data extraction and web navigation have evolved dramatically over the last decade. Among the various methodologies and niche concepts that pop up in data engineering circles, The Macon List Crawling Zeal stands out as a fascinating approach to structured data collection. Whether you are an experienced data scientist, an SEO professional, or an inquisitive hobbyist, understanding this concept can significantly sharpen your approach to gathering large-scale information from the web.
At its core, this phrase represents an energetic, systematic dedication to harvesting, verifying, and organizing lists from targeted online repositories. Instead of random scraping, it emphasizes meticulous planning, efficient traversal algorithms, and a relentless drive for data integrity. In this guide, we will unpack what it means, why it matters, and how you can apply these principles to your own digital projects.
Core Principles of Modern Web Crawling
Before diving into the specifics of The Macon List Crawling Zeal, it helps to establish a baseline of how web crawlers operate in the modern ecosystem. A crawler is essentially an automated script or bot that systematically browses the World Wide Web, typically for the purpose of web indexing or specific data harvesting.
Efficiency and Rate Limiting
One of the foundational rules of responsible crawling is respecting server resources. When you execute a high-volume data collection project, unchecked requests can easily overwhelm a target server, resulting in IP bans or server downtime. A zealous approach to crawling does not mean reckless speed; rather, it means intelligent efficiency. Implementing proper rate limits, exponential backoff strategies, and asynchronous requests ensures that your crawler gathers data swiftly without causing disruption.
Data Parsing and Cleaning
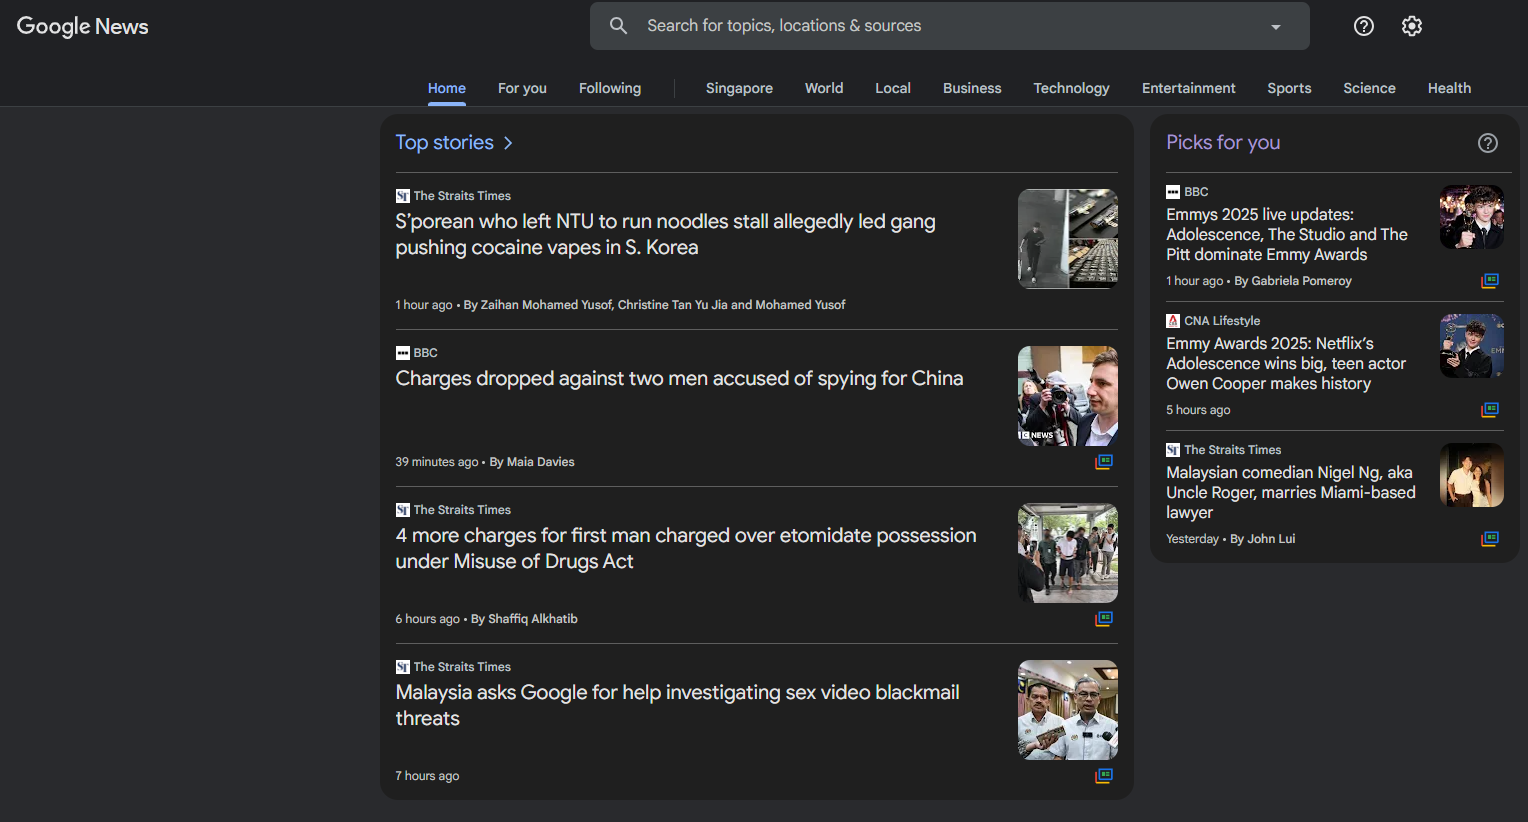
Raw HTML is messy. The true value of any crawling operation lies in the transformation of unstructured markup into clean, actionable datasets (such as CSV, JSON, or SQL databases). Utilizing robust parsing libraries like BeautifulSoup, Scrapy, or Cheerio allows you to extract precisely what you need while discarding boilerplate text, advertisements, and navigation menus.
Implementing The Macon List Crawling Zeal in Your Workflow
Adopting this meticulous mindset requires a structured framework. If you want to elevate your data extraction projects from basic scripts to high-performance pipelines, consider implementing the following step-by-step methodology.
- Define Your Scope: Clearly outline what lists you need to crawl. Avoid scope creep by specifying exact data points, such as titles, URLs, metadata, and timestamps.
- Audit Target Structures: Inspect the HTML and API endpoints of your target websites. Understanding pagination, infinite scrolls, and dynamic JavaScript rendering will save you hours of debugging later.
- Build Resilient Scripts: Incorporate error-handling mechanisms. Network timeouts, changing DOM structures, and CAPTCHAs are inevitable. Your crawler should log errors gracefully and allow for resumption without data loss.
- Validate and Store: Never trust raw scraped data at face value. Run automated validation checks to ensure fields aren't empty and formats match your schema before writing to your database.
Best Practices and Ethical Considerations
With great power comes great responsibility. Web scraping sits in a unique legal and ethical gray area, making adherence to best practices paramount for long-term success.
- Always Check robots.txt: This file tells search engine crawlers which pages the site owner does not want accessed. While not legally binding in all jurisdictions, respecting it is a hallmark of professional etiquette.
- Identify Your Bot: Configure your user-agent string to accurately reflect who you are and provide a contact email. Transparency builds trust with web administrators.
- Comply with Privacy Laws: Ensure your scraping activities do not harvest Personally Identifiable Information (PII) in violation of regulations like GDPR or CCPA.
Conclusion
The pursuit of clean, comprehensive data requires both technical skill and disciplined execution. By embracing the philosophy behind The Macon List Crawling Zeal, you can transform how you approach web scraping projects. Focus on efficiency, respect server limits, maintain rigorous data hygiene, and always operate within ethical boundaries to build sustainable data pipelines that stand the test of time.