Understanding Provisioning s Caus in Systems
Introduction to Provisioning s Caus

In modern IT infrastructure and cloud computing, efficient deployment relies heavily on specialized workflows and configurations. When administrators talk about provisioning s caus, they are often addressing the underlying mechanics, triggers, and causal relationships that dictate how digital resources are allocated, scaled, and managed.
Understanding these foundational triggers is essential for maintaining reliable, high-performing systems. Whether you are managing virtual machines, containerized workloads, or database clusters, recognizing how actions lead to specific state changes prevents bottlenecks and reduces downtime.
The Core Mechanics of Provisioning s Caus
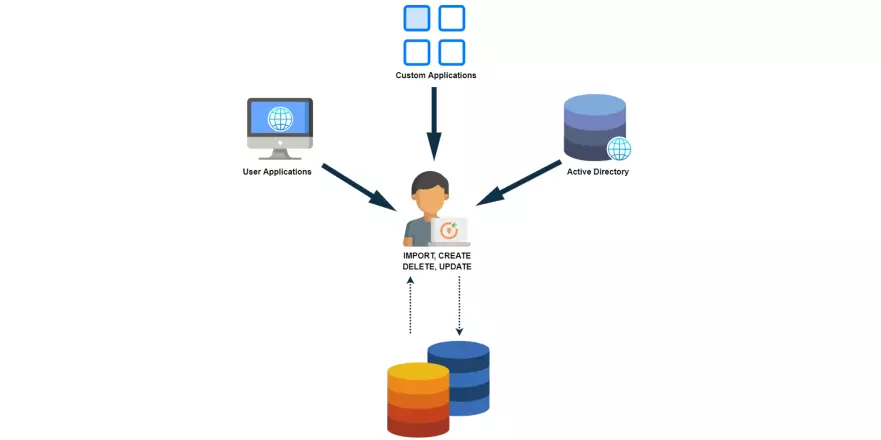
To grasp how automated and manual resource allocation functions, we must examine the sequence of events that trigger system changes. Provisioning involves preparing and equipping infrastructure to allow users or systems to use data and services. When we evaluate the causal factors behind these actions, several key components emerge.
Triggers and Event-Driven Architecture
Modern cloud environments rarely rely solely on manual intervention. Instead, they use event-driven architectures where specific inputs—such as a surge in web traffic or a newly deployed code repository—act as the root cause for automated scaling scripts to initiate.
- API Requests: Programmatic calls from developers or CI/CD pipelines demand immediate resource creation.
- Metric Thresholds: CPU utilization crossing a specific percentage automatically triggers scaling policies.
- Scheduled Events: Cron jobs and time-based triggers prepare infrastructure ahead of expected peak hours.
Dependency Chains and Resource Sequencing
Resources rarely exist in a vacuum. Allocating a web application server requires a pre-existing network configuration, storage volumes, and security group rules. In the context of provisioning s caus, identifying the correct sequence of dependencies ensures that child resources are never created before their parent dependencies are fully healthy and responsive.
Common Challenges and Bottlenecks
Video: What is Provisioning in IT?

Even with advanced automation tools, deployment pipelines frequently encounter friction. Misconfigured dependencies or inaccurate causal triggers can lead to cascading failures across your infrastructure stack.
Orchestration Failures
When multiple systems attempt to modify infrastructure simultaneously without proper locking mechanisms, race conditions occur. This can leave databases half-initialized or networks missing crucial routing tables. Utilizing declarative infrastructure-as-code (IaC) tools helps mitigate these risks by defining the desired end state rather than just the step-by-step procedural actions.
Debugging Causal Loops
Sometimes, an automated provisioning script responds to a metric that its own initialization process affects. This creates a feedback loop where resources continually spin up and spin down, consuming API quotas and driving up cloud bills. Comprehensive logging and rate-limiting are vital to catch these anomalies early.
Best Practices for Efficient Resource Deployment
Optimizing your infrastructure workflows requires a proactive approach to architecture and monitoring. By implementing industry standards, you can ensure predictable, reliable deployments every time.
- Adopt Infrastructure as Code (IaC): Tools like Terraform, Ansible, and AWS CloudFormation allow you to version-control your infrastructure definitions, making the causal relationship between your code and deployed assets transparent.
- Implement Thorough Testing: Run staging environments that mirror production to validate how your system handles automated scaling triggers and provisioning events.
- Monitor and Trace: Utilize modern observability platforms to trace API calls and infrastructure changes in real time, making it easier to pinpoint the exact root cause of any deployment failure.
Conclusion
Mastering the intricacies of provisioning s caus empowers engineering teams to build resilient, scalable architectures. By understanding the triggers, managing dependencies carefully, and leveraging modern automation tools, organizations can eliminate deployment friction and maintain seamless digital operations.