Unlock the HIDDEN Power of Your List Crawler Today!
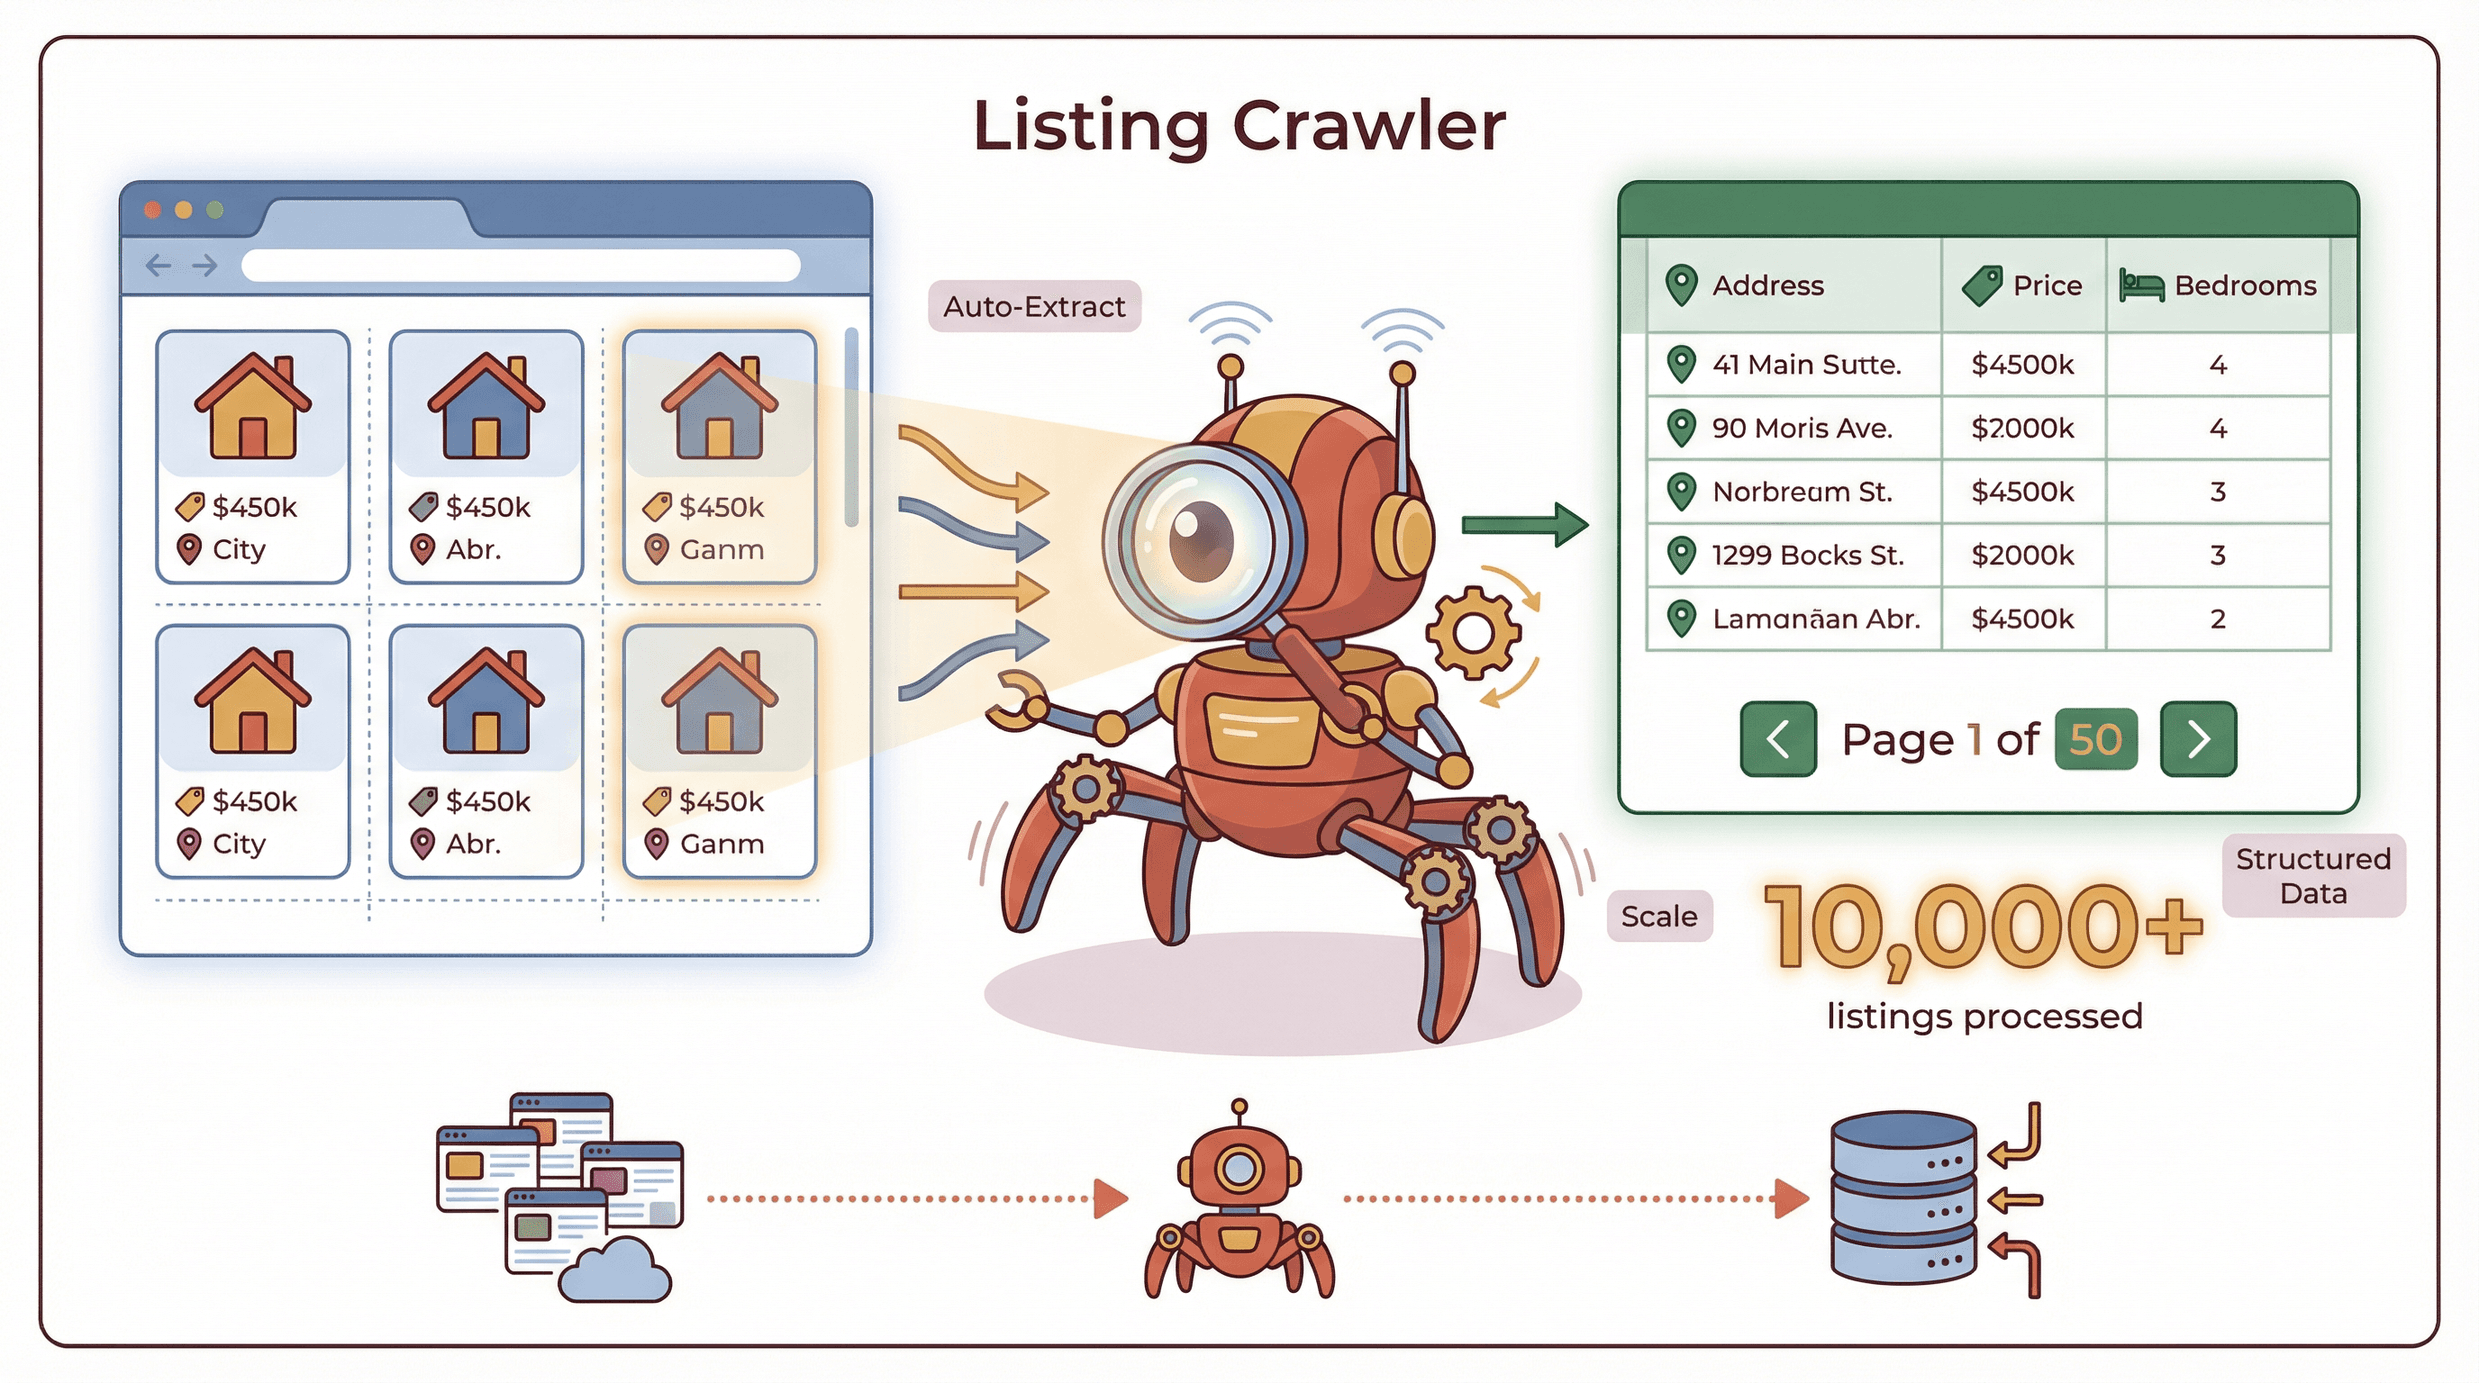
When most digital marketers and developers set up a web scraper, they treat it like a simple vacuum cleaner. It sucks up URLs, grabs basic HTML, and drops the data into a spreadsheet. But if you want to gain a true competitive advantage, you need to unlock the hidden power of your list crawler today and move beyond basic data harvesting.

Modern list crawlers are capable of much more than surface-level link collection. When configured correctly, they act as intelligence engines that can fuel your SEO audits, monitor competitor movements, and automate tedious lead generation workflows. Let us explore how you can stop using your crawler at a fraction of its capacity and start extracting maximum value from every single run.
Moving Beyond Basic URL Collection
The biggest mistake users make is stopping at the URL list. A standard crawl gives you a list of pages, but true insights lie beneath the surface structure. By shifting your mindset from mere collection to deep data extraction, you turn a simple directory into a dynamic database.
Capture Contextual Metadata
Do not just collect links; capture the surrounding context. Modify your crawler settings to pull meta descriptions, H1 tags, response headers, and schema markup simultaneously. Having this context immediately saves you hours of secondary crawling when you need to diagnose site-wide issues or analyze competitor content strategies.
Track Content Changes Over Time
A list crawler becomes infinitely more powerful when run on a recurring schedule. By comparing today's crawl results with last week's, you instantly spot:
- Newly published pages on competitor sites
- Silently deleted product pages or broken links
- Sudden shifts in pricing or product descriptions
- Unannounced updates to competitor terms or features
How to Unlock the HIDDEN Power of Your List Crawler Today
To truly maximize your tooling, you must implement advanced configurations that most users ignore. Here is how to upgrade your workflow right now.
1. Integrate Custom Regex Filters
Stop drowning in irrelevant data. If you are hunting for specific patterns—such as email addresses, specific product SKUs, or particular keyword mentions—write custom Regular Expressions (Regex) directly into your crawler rules. This ensures your output file contains only high-value, actionable intelligence rather than gigabytes of site bloat.
2. Leverage Headless Browsing for JavaScript-Heavy Sites
Many modern websites load content dynamically via JavaScript. If your crawler only reads the initial static HTML, you are missing half the picture. Enable headless browser rendering within your crawler settings to:
- Execute scripts and load fully rendered DOM trees
- Capture dynamically loaded pricing and inventory
- Scrape infinite-scroll pages without missing items
- Extract user reviews that load after the initial page load
3. Automate API Connections and Webhooks
Don't let your crawled data sit idle in a local CSV file. Connect your crawler directly to your project management tools, CRM, or data warehouse using webhooks and APIs. Imagine running a crawl that automatically populates a Trello board with broken links or pushes fresh leads straight into your sales pipeline without manual intervention.
Best Practices for Efficient and Ethical Crawling
Unlocking advanced features comes with responsibility. If you push your crawler too hard, you risk getting blocked, overloading target servers, or violating terms of service.
Respect Robots.txt and Rate Limiting
Always configure polite crawling rules. Set appropriate request delays (throttling) to mimic human browsing behavior and avoid hammering small servers. Furthermore, ensure your crawler respects robots.txt files unless you have explicit permission to audit the entire directory structure.
Rotate Proxies and User-Agents
For large-scale projects, single-IP crawling will quickly lead to CAPTCHAs and bans. Implement a reliable proxy rotation service and randomize your User-Agent strings. This keeps your crawler running smoothly, ensuring uninterrupted data flow for your critical business operations.
Conclusion
Your list crawler is far more than a basic link collector—it is a versatile engine for market intelligence, SEO mastery, and workflow automation. By moving past default settings, incorporating regex filters, leveraging headless browsing, and automating your data pipelines, you can completely transform how your business gathers digital insights. Take action, upgrade your configuration, and start getting deeper value from your data today.